meeting 7/25
Last edited: August 8, 2025meeting 8/1
Last edited: August 8, 2025Updates
- dropping dropout: https://proceedings.mlr.press/v202/geiping23a/geiping23a.pdf
- CAW-coref: revised! do we need more space for things such as a figure?
- stanza 1.9.0 staged! https://huggingface.co/stanfordnlp/stanza-en
Yay mend works!
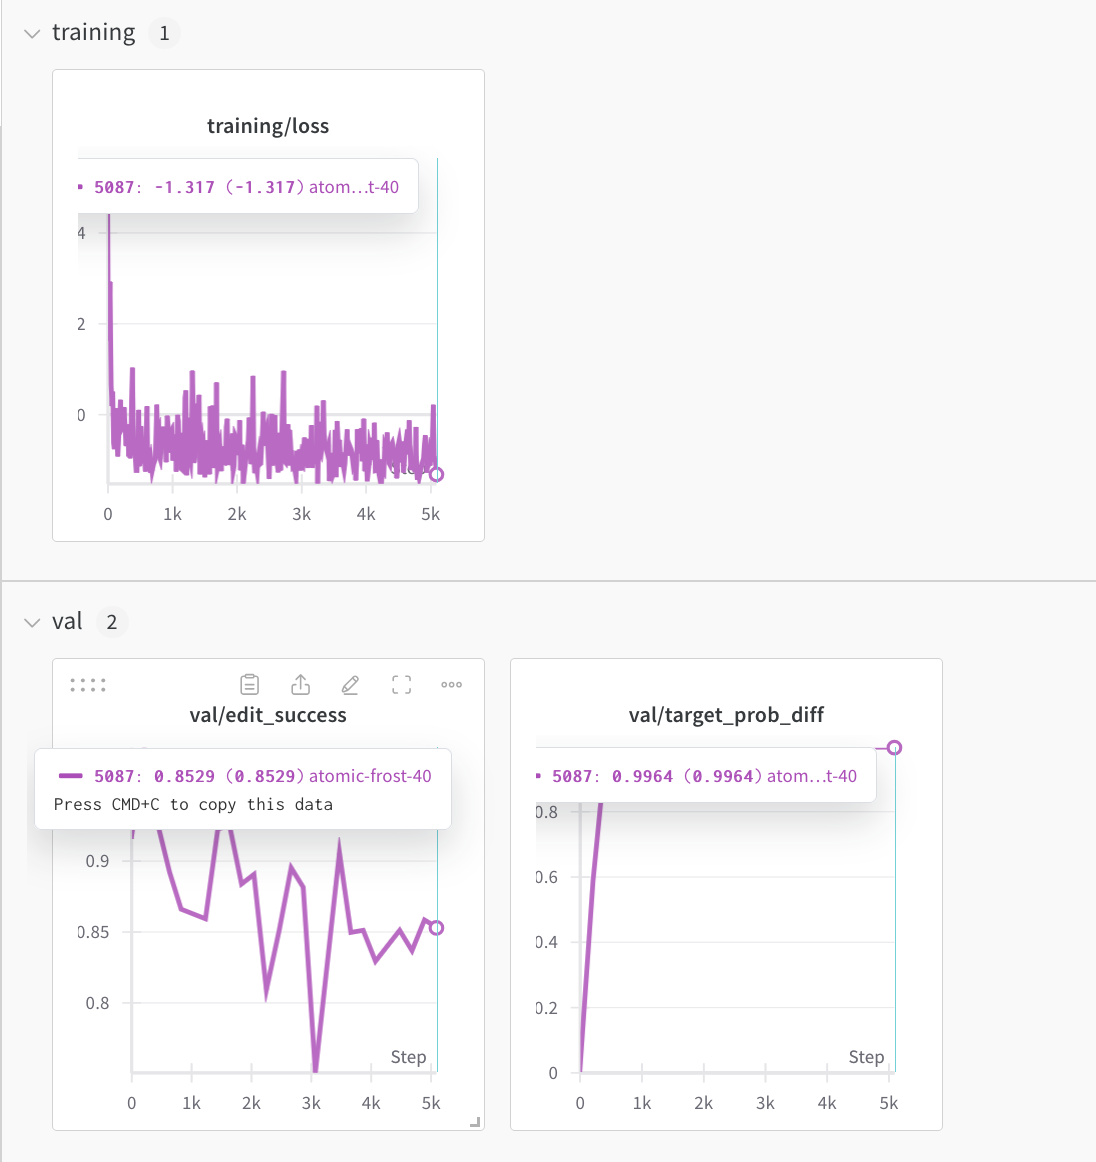
.mean() vs. .sum() for the dW maps?
PPL Isn’t the Only Possible Metric
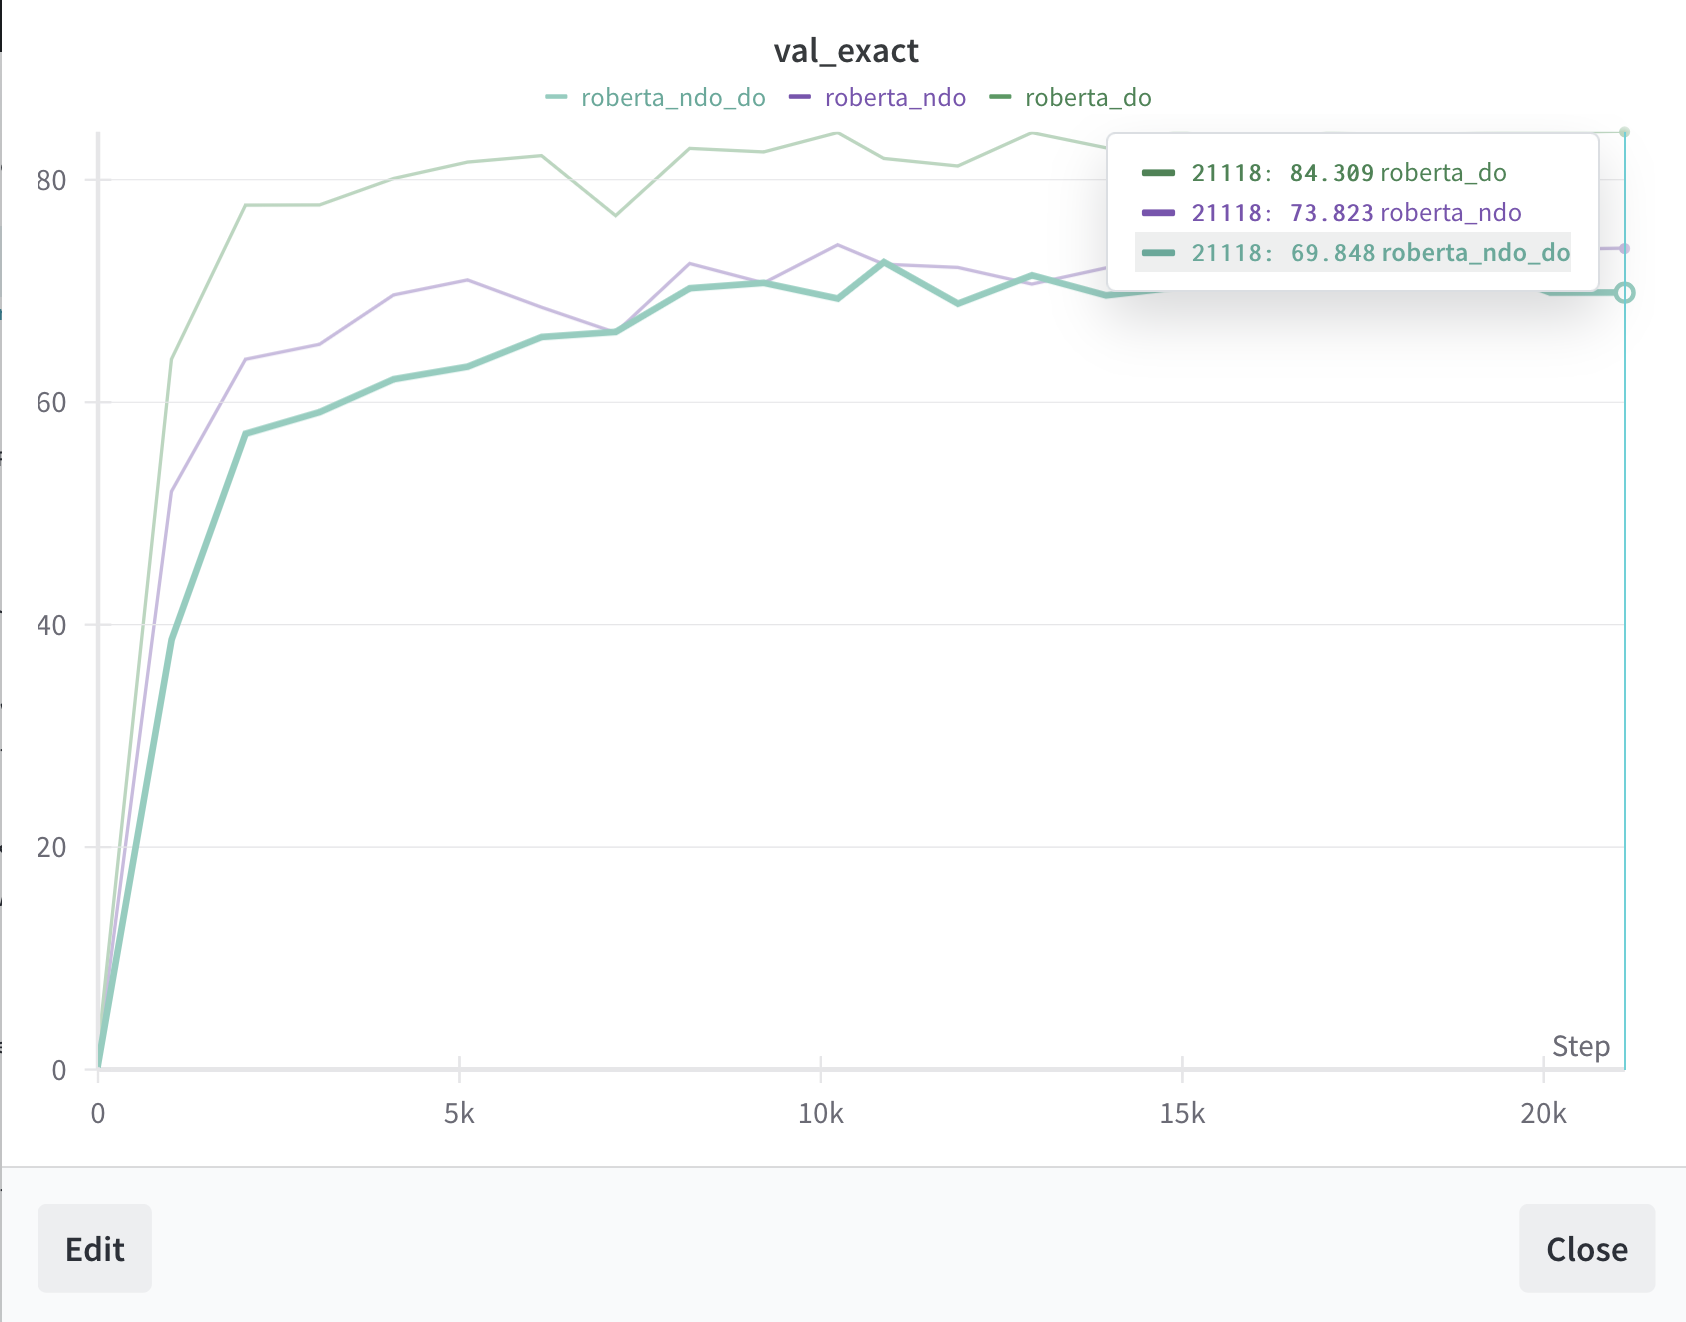
even if our model is better ppl, its worse at squad than Facebook (granted its been trained a lot less); will run with new pretraining model (expect that no dropout will be better (see paper above)).
Meghanani 2021
Last edited: August 8, 2025DOI: 10.3389/fcomp.2021.624558
One-Liner
analyzed spontaneous speech transcripts (only!) from TD and AD patients with fastText and CNN; best was \(83.33\%\) acc.
Novelty
- threw the NLP kitchen sink to transcripts
- fastText
- CNN (with vary n-gram kernel 2,3,4,5 sizes)
Notable Methods
- embeddings seaded by GloVe
- fastText are much faster, but CNN won out
Key Figs
the qual results
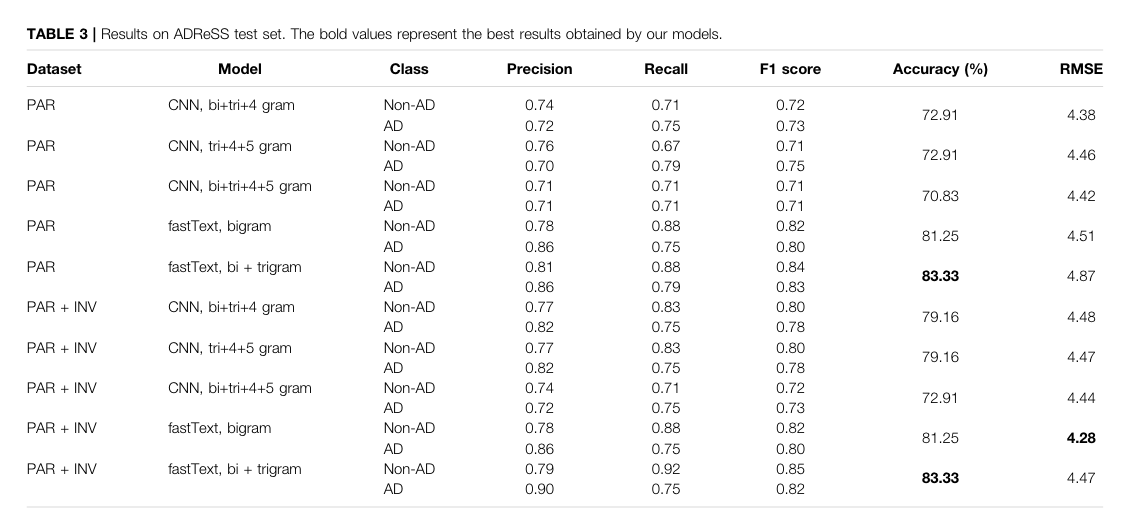
PAR (participant), INV (investigator)
Notes
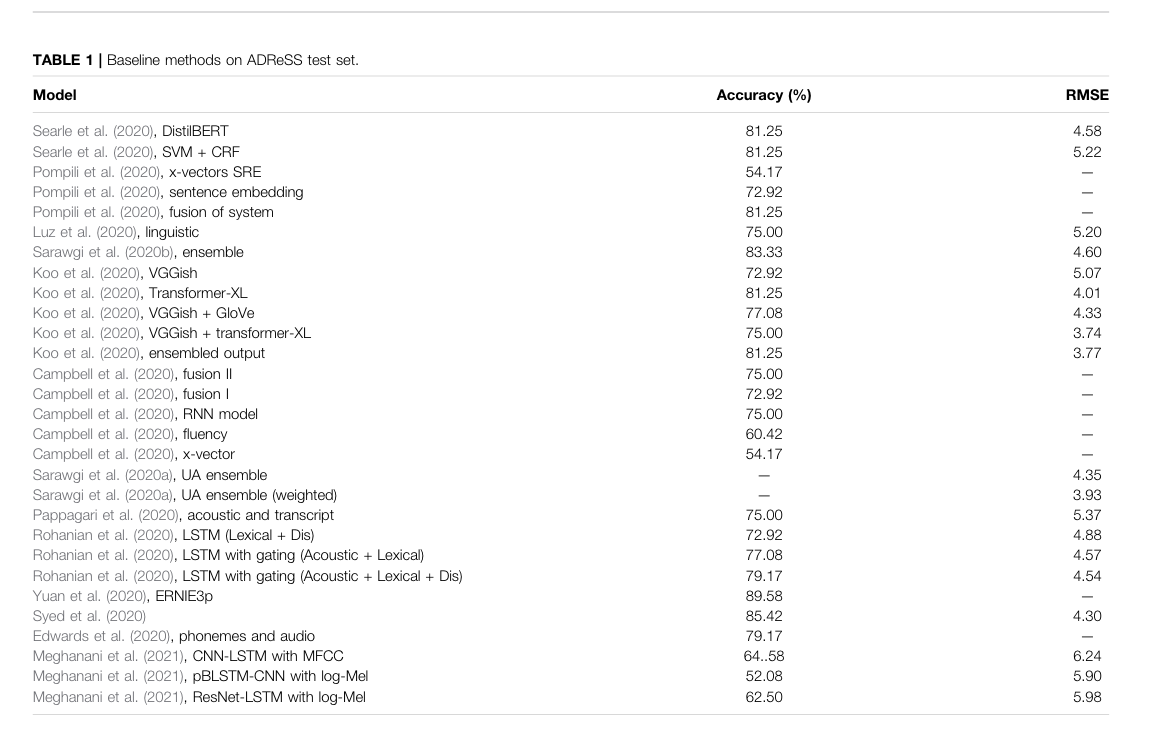
Hey look a review of the field:
Mel Scale
Last edited: August 8, 2025Human do not perceive frequency very well. The Mel scale is a scale from Hertz to what’s better perceived.