Spark
Last edited: August 8, 2025Spark is not a database. Importantly, its a “framework” of data:
- Programming platform
- Distributed file system
- Prallel execution environment
- Software ecosystem
It gives you the “parallel” search/sort needed to navigate a large database. It is based on the Hadoop ecosystem. Spark operates on RDDs to do lazy-evaluation.
Quickstart
When we start up Spark Shell, it will build you a sc variable which is appropriate for your supercomputer; if you are not, you need to set up the context yourself using the 3 lines noted below to make sc variable:
Sparse Sampling
Last edited: August 8, 2025Same core algorithm as Forward Search, but instead of calculating a utility based on the action-value over all possible next states, you make \(m\) different samples of next state, action, and reward, and average them
sparsity
Last edited: August 8, 2025A bunch of matricies could be sparse; for fluid dynamics, for instance, has a \(10^{6} \times 10^{6}\) matrix, but may only have \(7 \times 10^{6}\) non-zero entries; but the inverse could be fully dense!
In these cases, we almost never want to form a in inverse if needed.
If we really need to invert this, performing a LU-Factorization is going to be a very good idea.
Speech Feature Extraction
Last edited: August 8, 2025take audio
calculate Mel Scale representation
apply a series of Filter Banks which attenuates the input to highlight groups of frequencies
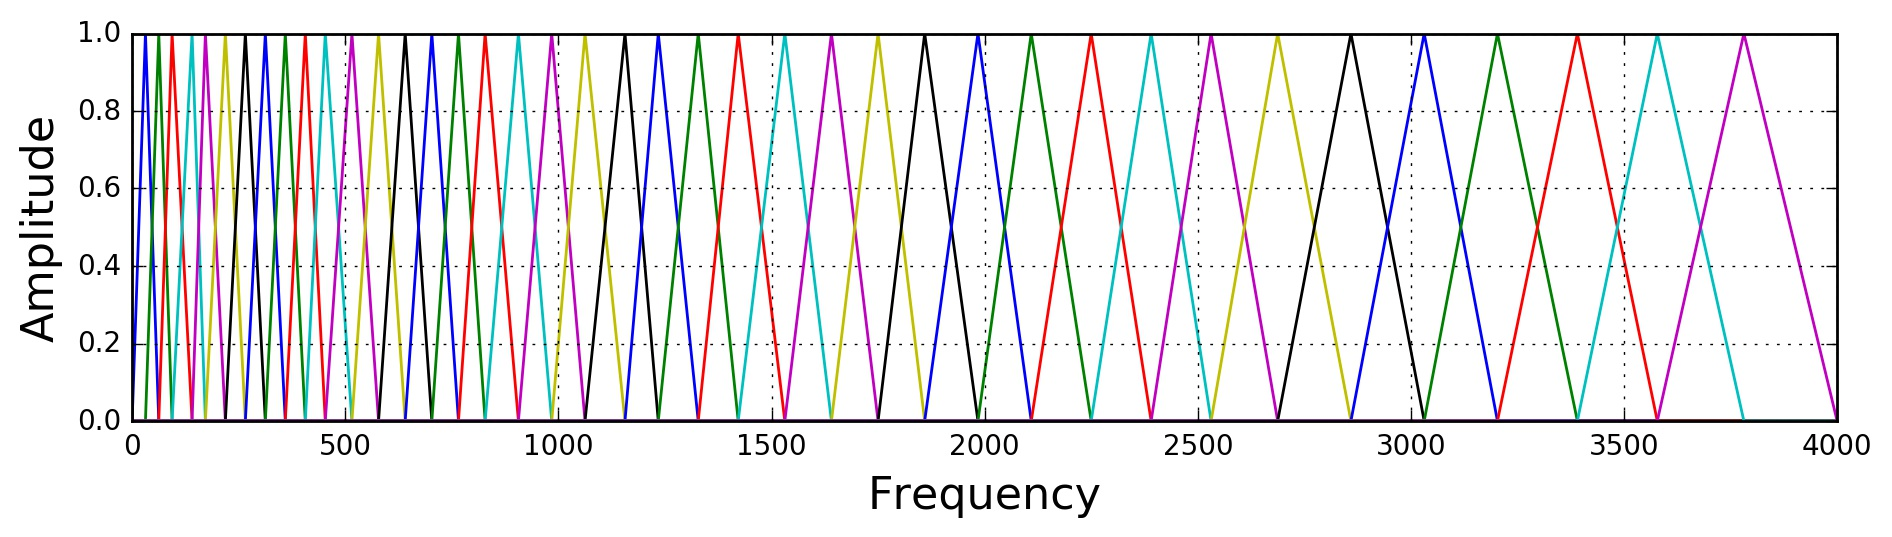
we then run a discrete-cosine transform to obtain MFCCs, because much of the output results will still correlate with each other